AI model benchmark
LiveGive AI models the same brief, then see the pages they actually built.
A public benchmark for how AI models do at building interactive web pages. Every model gets the same brief; each page is opened in a real browser and scored, with its time, token count and cost. You can open every page exactly as the model wrote it.
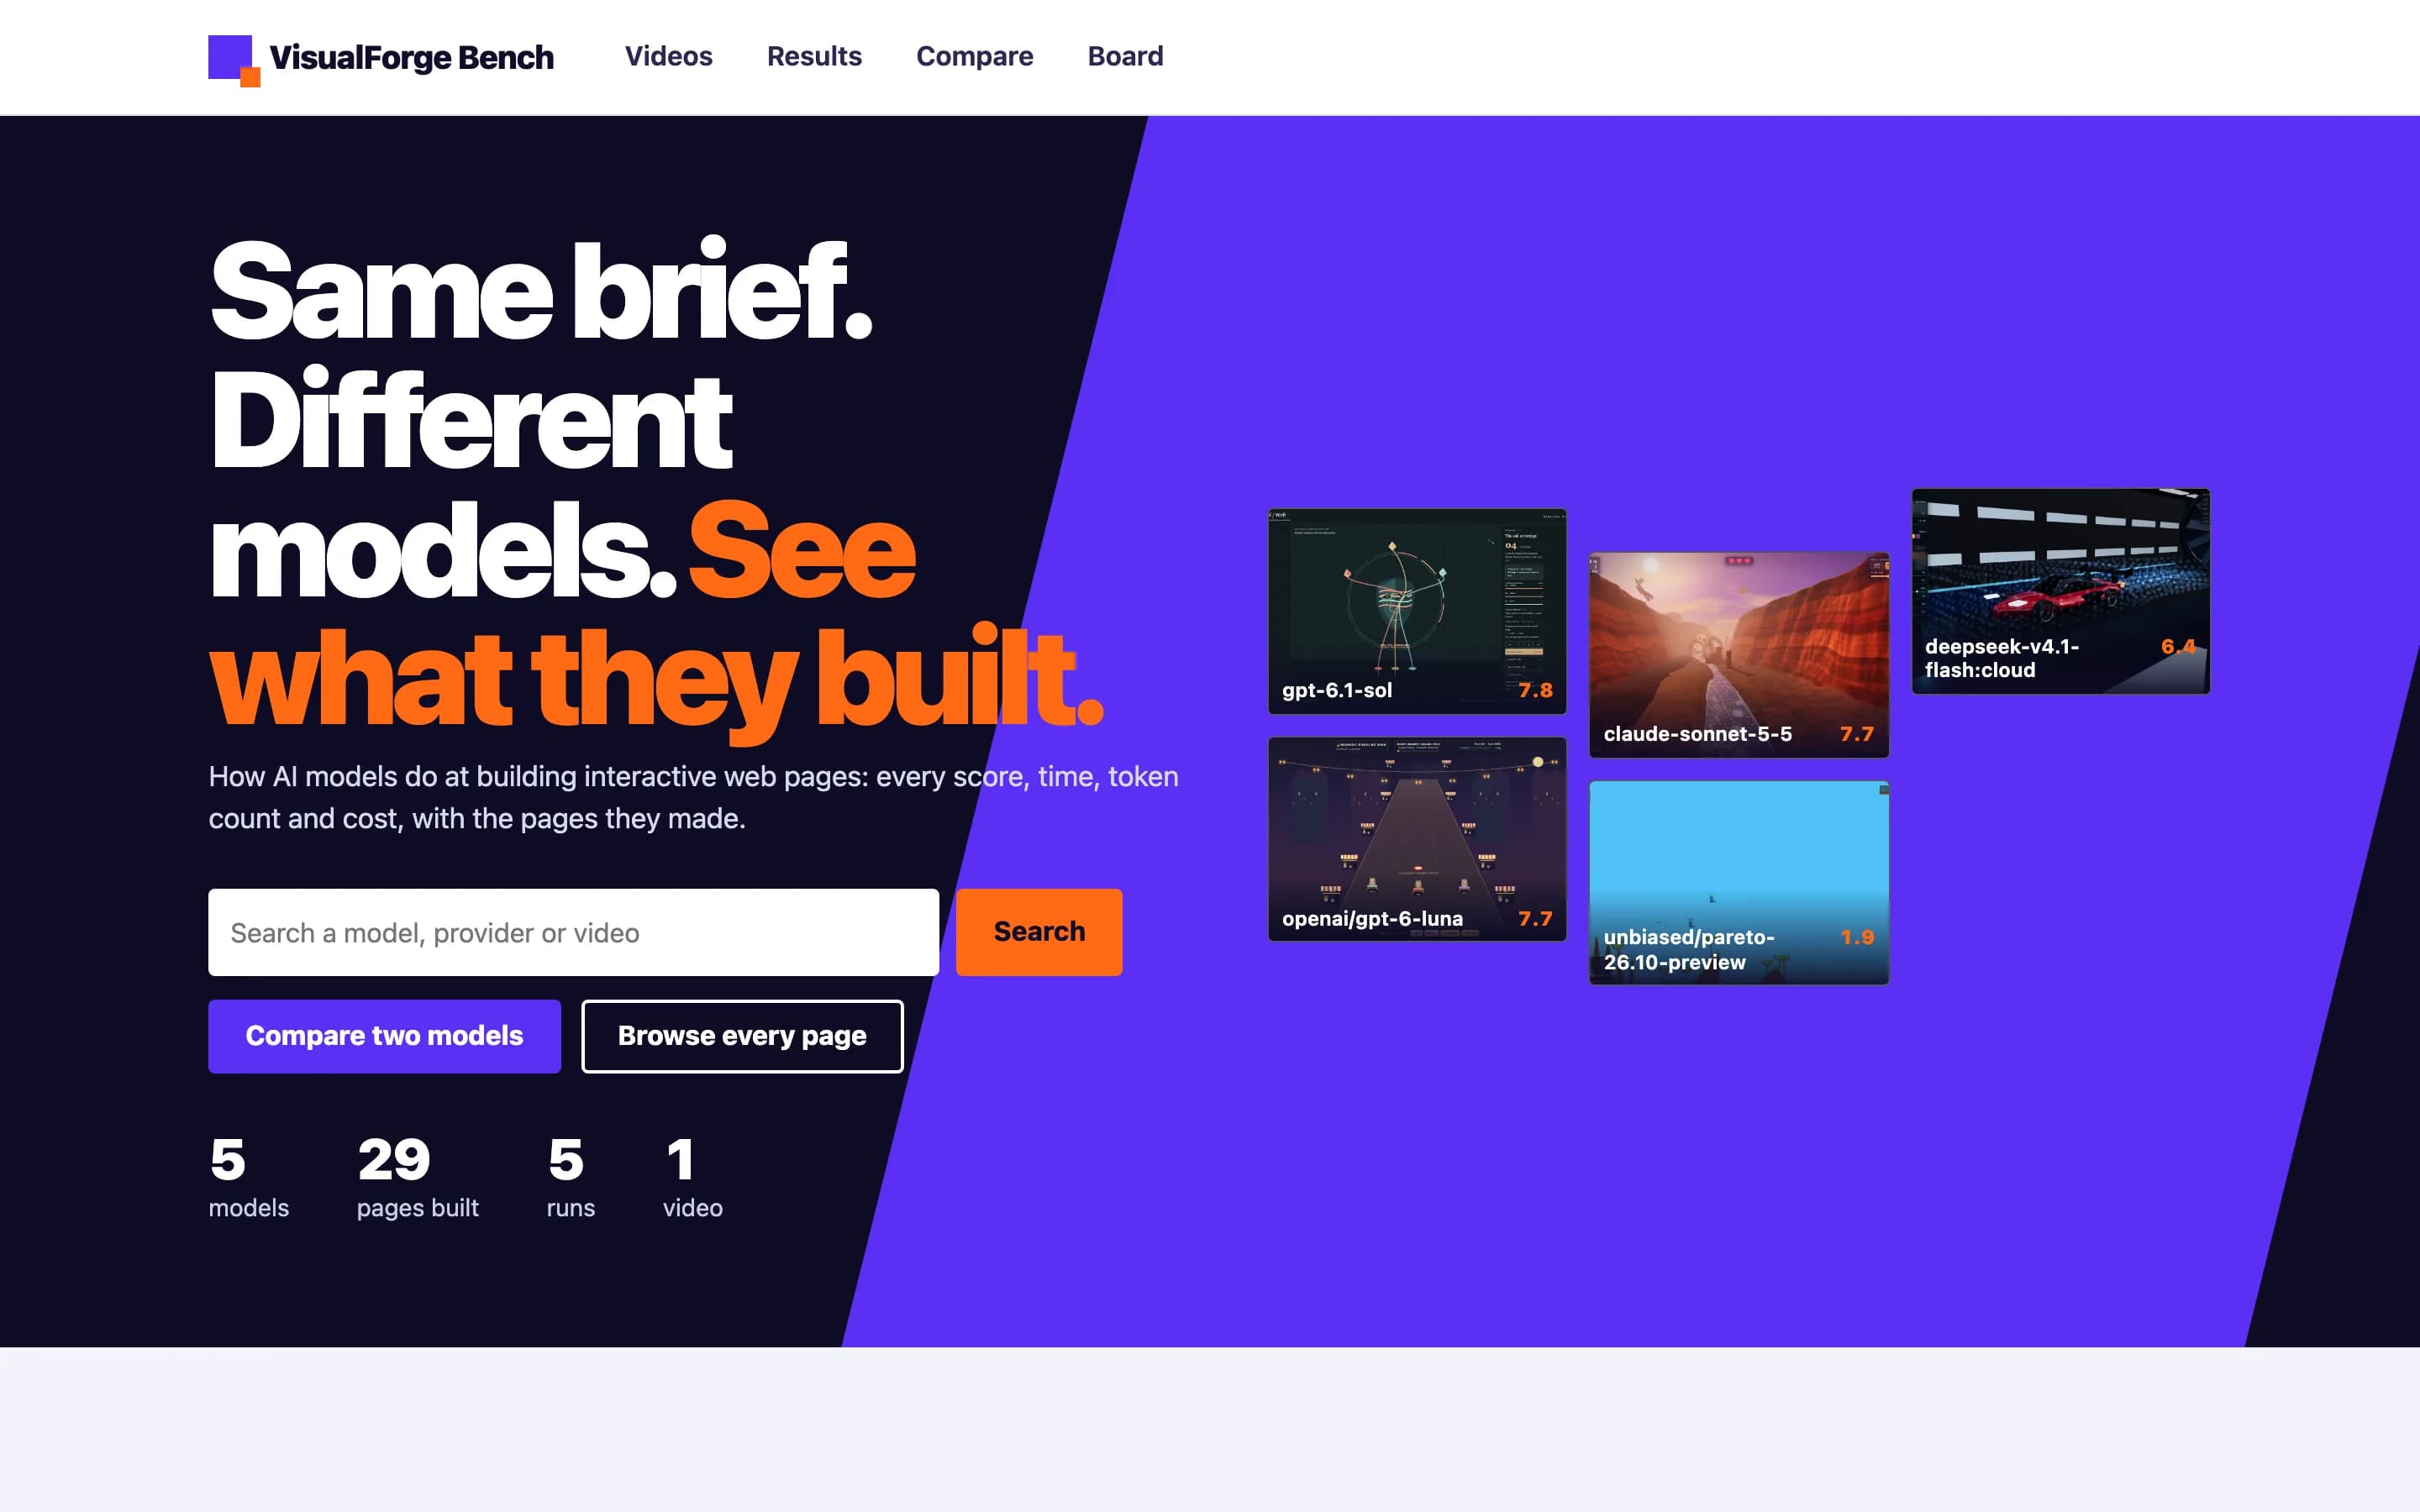
A benchmark score tells you which model did better, but not what it actually built. The page itself, mistakes included, says far more.
The decisions that shaped it.
- 01
Give every model the same brief and show each page exactly as the model wrote it.
- 02
Open every page in a real browser before scoring it, so the score reflects what actually runs.
- 03
Keep the prompts and scoring criteria private, and show a fingerprint of each prompt so you can tell when two runs had the same brief.
What had to work together.
- Test runner for hosted and local models
- Browser rendering and scoring
- Ranked board, with score against tokens and time
- Public run pages and video pages
Where the AI stops, and what happens when it is wrong.
- 01
Pages written by the models run in a sandbox, apart from the rest of the site
- 02
Estimates are marked as estimates, and figures that were not measured are left blank
- 03
A run goes public only when I update the website, never automatically
What you can check today.
- Live at visualforgebench.com
- Every page viewable exactly as each model wrote it
- Scores downloadable as a CSV file
Status: Live. I do not claim users, customers or performance numbers unless they are written here.
Talk about a similar problem ↗